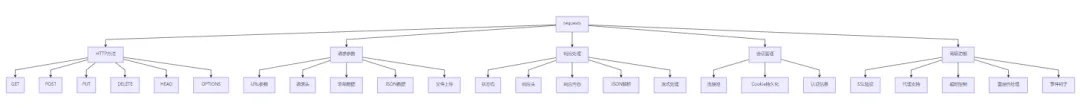
1. 创始时间与作者
2. 官方资源
GitHub 地址:https://github.com/psf/requests
PyPI 地址:https://pypi.org/project/requests/
文档地址:https://docs.python-requests.org/
官方主页:https://python-requests.org
3. 核心功能
4. 应用场景
1. 基础HTTP请求
import requests# GET请求 - 获取数据response = requests.get('https://api.github.com')print(f"状态码: {response.status_code}")print(f"响应头: {dict(response.headers)}")print(f"响应内容: {response.text[:200]}...")# 带参数的GET请求params = {'q': 'python', 'page': 1, 'per_page': 10}response = requests.get('https://api.github.com/search/repositories', params=params)data = response.json()print(f"找到 {data['total_count']} 个仓库")# POST请求 - 提交数据data = {'username': 'testuser', 'password': 'testpass'}response = requests.post('https://httpbin.org/post', data=data)print(f"POST响应: {response.json()}")# 带JSON数据的POST请求json_data = {'name': 'John', 'age': 30, 'city': 'New York'}response = requests.post('https://httpbin.org/post', json=json_data)print(f"JSON POST响应: {response.json()}")2. 高级请求处理
import requestsimport jsondef advanced_requests_demo():"""高级请求功能演示"""# 自定义请求头headers = {'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36','Accept': 'application/json','Authorization': 'Bearer your-token-here' }# 带超时设置try:response = requests.get('https://httpbin.org/delay/5', headers=headers,timeout=3# 3秒超时 )except requests.exceptions.Timeout:print("请求超时!")return# 文件上传files = {'file': ('test.txt', open('test.txt', 'rb'), 'text/plain'),'image': ('image.jpg', open('image.jpg', 'rb'), 'image/jpeg') }response = requests.post('https://httpbin.org/post', files=files)print(f"文件上传响应: {response.json()}")# 流式下载大文件response = requests.get('https://httpbin.org/stream/100', stream=True)for i, line in enumerate(response.iter_lines()):if i>= 5: # 只显示前5行breakif line:print(f"流式数据 {i}: {line.decode('utf-8')}")# 运行示例advanced_requests_demo()3. 会话管理与Cookie处理
import requestsclass WebSessionManager:"""Web会话管理器"""def __init__(self):self.session = requests.Session()# 设置默认请求头self.session.headers.update({'User-Agent': 'Mozilla/5.0 (Windows NT 10.0; Win64; x64) AppleWebKit/537.36','Accept': 'application/json' })def login(self, username, password):"""模拟登录"""login_data = {'username': username,'password': password }response = self.session.post('https://httpbin.org/post',data=login_data )if response.status_code == 200:print("登录成功")# 保存登录后的Cookieself.save_cookies()return Truereturn Falsedef save_cookies(self):"""保存Cookie到文件"""import picklewith open('cookies.pkl', 'wb') as f:pickle.dump(self.session.cookies, f)print("Cookie已保存")def load_cookies(self):"""从文件加载Cookie"""import pickletry:with open('cookies.pkl', 'rb') as f:self.session.cookies.update(pickle.load(f))print("Cookie已加载")return Trueexcept FileNotFoundError:print("未找到Cookie文件")return Falsedef get_protected_resource(self, url):"""获取需要认证的资源"""response = self.session.get(url)if response.status_code == 200:return response.json()else:print(f"请求失败: {response.status_code}")return Nonedef close(self):"""关闭会话"""self.session.close()def session_demo():"""会话管理演示"""manager = WebSessionManager()try:# 模拟登录if manager.login('testuser', 'testpass'):# 使用会话访问多个资源resources = ['https://httpbin.org/cookies','https://httpbin.org/headers','https://httpbin.org/ip' ]for resource in resources:data = manager.get_protected_resource(resource)if data:print(f"资源 {resource}: {data}")# 显示会话信息print(f"会话Cookie: {dict(manager.session.cookies)}")print(f"会话头信息: {dict(manager.session.headers)}")finally:manager.close()# 运行示例session_demo()4. 错误处理与重试机制
import requestsfrom requests.adapters import HTTPAdapterfrom requests.packages.urllib3.util.retry import Retryimport timeclass RobustRequestClient:"""健壮的请求客户端"""def __init__(self, max_retries=3, backoff_factor=0.5):self.session = requests.Session()self.setup_retry_strategy(max_retries, backoff_factor)def setup_retry_strategy(self, max_retries, backoff_factor):"""设置重试策略"""retry_strategy = Retry(total=max_retries,backoff_factor=backoff_factor,status_forcelist=[429, 500, 502, 503, 504],allowed_methods=["GET", "POST", "PUT", "DELETE"] )adapter = HTTPAdapter(max_retries=retry_strategy)self.session.mount("http://", adapter)self.session.mount("https://", adapter)def make_request(self, method, url, **kwargs):"""发送请求并处理错误"""start_time = time.time()try:response = self.session.request(method, url, **kwargs)response.raise_for_status() # 如果状态码不是200,抛出HTTPErrorend_time = time.time()print(f"请求成功: {method} {url} - 状态码: {response.status_code} - 耗时: {end_time - start_time:.2f}s")return responseexcept requests.exceptions.HTTPError as err:print(f"HTTP错误: {err}")except requests.exceptions.ConnectionError as err:print(f"连接错误: {err}")except requests.exceptions.Timeout as err:print(f"超时错误: {err}")except requests.exceptions.RequestException as err:print(f"请求异常: {err}")return Nonedef download_file(self, url, filepath, chunk_size=8192):"""下载文件并显示进度"""response = self.session.get(url, stream=True)if response.status_code == 200:total_size = int(response.headers.get('content-length', 0))downloaded = 0with open(filepath, 'wb') as f:for chunk in response.iter_content(chunk_size=chunk_size):if chunk:f.write(chunk)downloaded += len(chunk)if total_size>0:progress = (downloaded/total_size) *100print(f"下载进度: {progress:.1f}%", end='\r')print(f"\n文件下载完成: {filepath}")return Trueelse:print(f"下载失败: {response.status_code}")return Falsedef robust_client_demo():"""健壮客户端演示"""client = RobustRequestClient(max_retries=3)# 测试各种请求test_cases = [ ('GET', 'https://httpbin.org/status/200'), ('GET', 'https://httpbin.org/status/404'), # 会失败 ('GET', 'https://httpbin.org/status/500'), # 会重试 ('POST', 'https://httpbin.org/post', {'data': {'test': 'value'}}), ]for test_case in test_cases:method, url = test_case[0], test_case[1]kwargs = test_case[2] if len(test_case) >2 else {}client.make_request(method, url, **kwargs)time.sleep(1) # 避免请求过快# 运行示例robust_client_demo()
5. 底层逻辑与技术原理
核心架构
关键技术
连接池管理:
使用urllib3的连接池
复用HTTP连接,减少TCP握手开销
自动处理连接超时和重试
请求处理流程:
# 1. 构建PreparedRequestrequest = Request(method, url, headers=headers, data=data).prepare()# 2. 发送请求response = self.send(request, **send_kwargs)# 3. 处理响应return Response(status_code=resp.status,headers=resp.headers,content=resp.data,request=request)
自动内容解码:
根据响应头自动解码内容
支持gzip、deflate压缩
自动处理字符编码
Cookie处理:
自动处理Set-Cookie头
会话间Cookie持久化
支持自定义Cookie策略
SSL/TLS支持:
6. 安装与配置
基础安装
pip install requests
可选依赖
# 安装安全相关的额外依赖pip install requests[security]# 安装Socks代理支持pip install requests[socks]
环境要求
| 组件 | 最低要求 | 推荐配置 |
|---|
| Python | 2.7+ 或 3.5+ | 3.6+ |
| 操作系统 | 任意 | 任意 |
| 网络 | 需要网络连接 | 稳定的网络连接 |
验证安装
import requestsprint(requests.__version__)# 简单测试response = requests.get('https://httpbin.org/get')print(f"测试请求状态码: {response.status_code}")
7. 性能指标
| 操作类型 | 执行时间 | 内存开销 | 适用场景 |
|---|
| 简单GET请求 | 100-500ms | 1-10MB | 常规API调用 |
| 会话请求 | 50-200ms | 5-20MB | 多次请求同一主机 |
| 大文件下载 | 依赖网络 | 可流式处理 | 文件下载 |
| 并发请求 | 依赖并发库 | 每个线程独立 | 高并发场景 |
8. 高级功能使用
1. 自定义认证
import requestsfrom requests.auth import AuthBaseclass BearerTokenAuth(AuthBase):"""自定义Bearer Token认证"""def __init__(self, token):self.token = tokendef __call__(self, request):request.headers['Authorization'] = f'Bearer {self.token}'return requestdef custom_auth_demo():"""自定义认证演示"""# 使用自定义认证auth = BearerTokenAuth('your-token-here')response = requests.get('https://httpbin.org/bearer', auth=auth)print(f"认证响应: {response.json()}")# 使用HTTP基本认证from requests.auth import HTTPBasicAuthbasic_auth = HTTPBasicAuth('username', 'password')response = requests.get('https://httpbin.org/basic-auth/user/pass', auth=basic_auth)print(f"基本认证响应: {response.json()}")# 运行示例custom_auth_demo()2. 代理设置
import requestsdef proxy_demo():"""代理演示"""proxies = {'http': 'http://10.10.1.10:3128','https': 'http://10.10.1.10:1080', }# 使用代理response = requests.get('https://httpbin.org/ip', proxies=proxies)print(f"通过代理的IP: {response.json()}")# SOCKS代理(需要安装requests[socks])# proxies = {# 'http': 'socks5://user:pass@host:port',# 'https': 'socks5://user:pass@host:port'# }# 运行示例(需要实际代理服务器)# proxy_demo()3. 事件钩子
import requestsdef hook_demo():"""事件钩子演示"""def print_url(r, *args, **kwargs):print(f"请求URL: {r.url}")def check_status(r, *args, **kwargs):r.raise_for_status()print("状态码正常")hooks = {'response': [print_url, check_status] }response = requests.get('https://httpbin.org/json',hooks=hooks )print("请求完成")# 运行示例hook_demo()4. 流式请求
import requestsimport jsondef streaming_demo():"""流式请求演示"""# 流式上传def generate_large_data():for i in range(10):yield json.dumps({'chunk': i, 'data': 'x'*100}).encode()response = requests.post('https://httpbin.org/post',data=generate_large_data(),headers={'Content-Type': 'application/json'} )print(f"流式上传响应: {response.json()}")# Server-Sent Events (SSE)response = requests.get('https://httpbin.org/stream/5', stream=True)for line in response.iter_lines():if line:data = json.loads(line.decode())print(f"SSE数据: {data}")# 运行示例streaming_demo()
9. 与同类工具对比
| 特性 | requests | urllib3 | httpx | aiohttp |
|---|
| API易用性 | ⭐⭐⭐⭐⭐ | ⭐⭐⭐ | ⭐⭐⭐⭐ | ⭐⭐⭐ |
| 同步支持 | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ | ❌ |
| 异步支持 | ❌ | ❌ | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ |
| HTTP/2 | ❌ | ❌ | ⭐⭐⭐⭐ | ⭐⭐⭐ |
| 性能 | ⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐ | ⭐⭐⭐⭐⭐ |
| 生态成熟度 | ⭐⭐⭐⭐⭐ | ⭐⭐⭐⭐ | ⭐⭐⭐ | ⭐⭐⭐⭐ |
10. 安全与最佳实践
安全建议
HTTPS验证:
# 始终验证SSL证书requests.get('https://example.com', verify=True)# 自定义CA证书包requests.get('https://example.com', verify='/path/to/certfile')敏感信息保护:
# 不要将凭据硬编码在代码中import osAPI_KEY = os.getenv('API_KEY')response = requests.get('https://api.example.com/data',headers={'Authorization': f'Bearer {API_KEY}'})输入验证:
def safe_request(url):# 验证URL格式if not url.startswith(('http://', 'https://')):raise ValueError("不安全的URL协议")return requests.get(url)
最佳实践
import requestsfrom requests.adapters import HTTPAdapterfrom requests.packages.urllib3.util.retry import Retrydef create_robust_session():"""创建健壮的会话"""session = requests.Session()# 重试策略retry_strategy = Retry(total=3,backoff_factor=1,status_forcelist=[429, 500, 502, 503, 504], )# 适配器配置adapter = HTTPAdapter(max_retries=retry_strategy,pool_connections=10,pool_maxsize=10 )session.mount("http://", adapter)session.mount("https://", adapter)# 默认配置session.headers.update({'User-Agent': 'MyApp/1.0','Accept': 'application/json' })return session# 使用示例with create_robust_session() as session:response = session.get('https://api.example.com/data')print(response.json())
11. 企业级应用案例
Web服务客户端
数据采集
自动化测试
云服务集成
AWS、Azure、GCP SDK底层
第三方API集成
移动应用后端
总结
requests 是 Python HTTP 客户端库的事实标准,核心价值在于:
简单易用:直观的API设计,几行代码完成复杂HTTP操作
功能全面:支持认证、Cookie、代理、SSL等高级功能
稳定可靠:经过多年生产环境验证,被数百万项目使用
生态丰富:庞大的用户群体和丰富的文档资源
技术亮点:
基于urllib3的连接池管理
自动内容解码和编码
灵活的会话和Cookie处理
完善的错误处理和重试机制
适用场景:
Web API调用和数据采集
自动化测试和监控
微服务和服务间通信
快速原型开发和脚本编写
安装使用:
pip install requests==2.31.0
学习资源:
官方文档:https://docs.python-requests.org/
快速上手:https://requests.readthedocs.io/en/latest/user/quickstart/
高级用法:https://requests.readthedocs.io/en/latest/user/advanced/
截至2023年,requests在GitHub收获 48k+ Star,月下载量超 1亿次,成为Python生态系统中最受欢迎的库之一。项目遵循 Apache 2.0 开源协议,可免费用于商业和非商业项目。