Python与数据库:高效数据存储与检索
- 2026-09-24 22:39:07
来源:网络
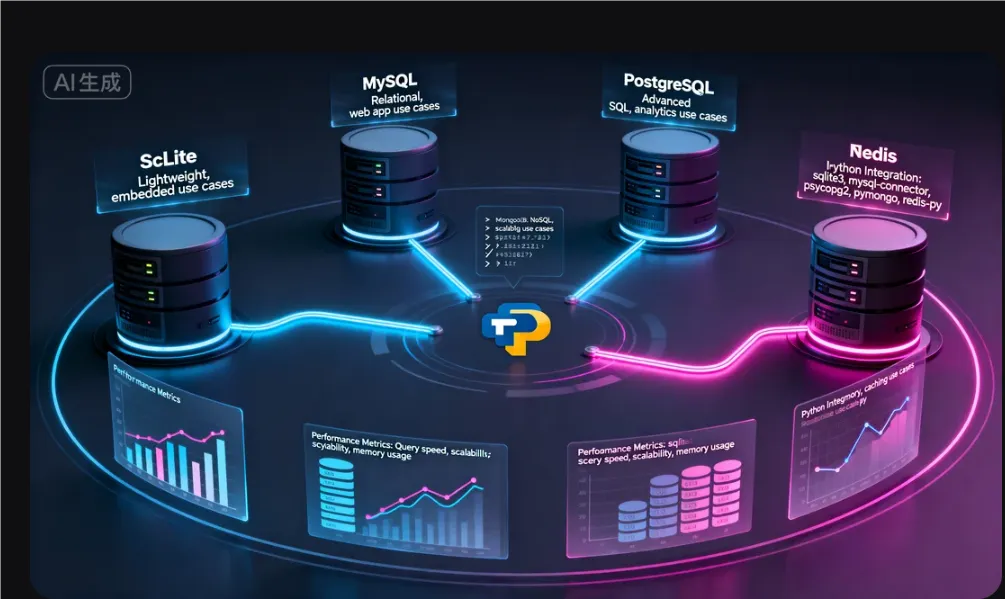
开头引言:
大家好,我是Python进阶者。在现代应用开发中,数据是核心,而数据库则是数据的家。Python作为数据科学和Web开发的首选语言,提供了丰富的数据库操作工具和框架。今天,我们将深入探索Python与数据库的交互世界,从基础的SQL操作到高级的ORM使用,从关系型数据库到NoSQL,帮助你构建高效、可靠的数据存储方案!
一、数据库基础与连接管理
1.1 数据库连接最佳实践
import sqlite3import mysql.connectorimport psycopg2from contextlib import contextmanager# SQLite连接示例defsqlite_connection_demo():"""SQLite数据库连接示例"""# 使用上下文管理器确保连接关闭with sqlite3.connect('example.db') as conn: cursor = conn.cursor()# 创建表 cursor.execute(''' CREATE TABLE IF NOT EXISTS users ( id INTEGER PRIMARY KEY AUTOINCREMENT, name TEXT NOT NULL, email TEXT UNIQUE NOT NULL, created_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP ) ''')# 插入数据 cursor.execute("INSERT INTO users (name, email) VALUES (?, ?)", ('张三', 'zhangsan@example.com') ) conn.commit()print("SQLite操作完成")# MySQL连接示例defmysql_connection_demo():"""MySQL数据库连接示例"""try: conn = mysql.connector.connect( host='localhost', user='your_username', password='your_password', database='test_db', charset='utf8mb4', connection_timeout=10 )with conn.cursor(dictionary=True) as cursor: # 返回字典格式 cursor.execute("SELECT version()") result = cursor.fetchone()print(f"MySQL版本: {result['version()']}")except mysql.connector.Error as e:print(f"MySQL连接错误: {e}")finally:if'conn'inlocals() and conn.is_connected(): conn.close()# PostgreSQL连接示例defpostgresql_connection_demo():"""PostgreSQL数据库连接示例"""try: conn = psycopg2.connect( host='localhost', user='your_username', password='your_password', dbname='test_db', connect_timeout=10 )with conn.cursor() as cursor: cursor.execute("SELECT version()") result = cursor.fetchone()print(f"PostgreSQL版本: {result[0]}")except psycopg2.Error as e:print(f"PostgreSQL连接错误: {e}")finally:if'conn'inlocals(): conn.close()# 通用数据库连接上下文管理器@contextmanagerdefget_db_connection(db_type='sqlite', **kwargs):"""通用的数据库连接上下文管理器""" conn = Nonetry:if db_type == 'sqlite': conn = sqlite3.connect(kwargs.get('database', ':memory:'))elif db_type == 'mysql': conn = mysql.connector.connect(**kwargs)elif db_type == 'postgresql': conn = psycopg2.connect(**kwargs)else:raise ValueError("不支持的数据库类型")yield connexcept Exception as e:print(f"数据库连接失败: {e}")raisefinally:if conn: conn.close()# 使用示例with get_db_connection('sqlite', database='test.db') as conn: cursor = conn.cursor() cursor.execute("SELECT sqlite_version()")print(f"SQLite版本: {cursor.fetchone()[0]}")
1.2 数据库连接池管理
from mysql.connector import poolingimport threadingimport timedefconnection_pool_demo():"""数据库连接池示例"""# 创建连接池 pool_config = {'pool_name': 'my_pool','pool_size': 5,'host': 'localhost','user': 'your_username','password': 'your_password','database': 'test_db' } connection_pool = pooling.MySQLConnectionPool(**pool_config)defworker(worker_id):"""工作线程函数"""try:# 从连接池获取连接 conn = connection_pool.get_connection()print(f"工作者 {worker_id} 获取连接")with conn.cursor() as cursor: cursor.execute("SELECT SLEEP(0.1)") # 模拟查询 cursor.fetchall()# 模拟工作 time.sleep(0.2)print(f"工作者 {worker_id} 释放连接")except Exception as e:print(f"工作者 {worker_id} 错误: {e}")finally:if'conn'inlocals(): conn.close()# 创建多个线程测试连接池 threads = []for i inrange(10): thread = threading.Thread(target=worker, args=(i,)) threads.append(thread) thread.start()for thread in threads: thread.join()print("连接池测试完成")print(f"连接池状态: {connection_pool.pool_name} 大小: {connection_pool.pool_size}")# 注意:实际使用时需要配置正确的数据库连接参数# connection_pool_demo()
二、SQL操作与性能优化
2.1 基础CRUD操作
defbasic_crud_operations():"""基础CRUD操作示例"""with sqlite3.connect('crud_demo.db') as conn: cursor = conn.cursor()# 创建表 cursor.execute(''' CREATE TABLE IF NOT EXISTS products ( id INTEGER PRIMARY KEY AUTOINCREMENT, name TEXT NOT NULL, price REAL NOT NULL, category TEXT, stock INTEGER DEFAULT 0, created_at TIMESTAMP DEFAULT CURRENT_TIMESTAMP ) ''')# 1. CREATE - 插入数据 products = [ ('笔记本电脑', 5999.99, '电子产品', 50), ('智能手机', 3999.99, '电子产品', 100), ('书籍', 49.99, '文化用品', 200), ('椅子', 299.99, '家具', 30) ] cursor.executemany("INSERT INTO products (name, price, category, stock) VALUES (?, ?, ?, ?)", products )# 2. READ - 查询数据print("=== 所有产品 ===") cursor.execute("SELECT * FROM products")for row in cursor.fetchall():print(row)print("\n=== 电子产品 ===") cursor.execute("SELECT name, price FROM products WHERE category = ?", ('电子产品',) )for row in cursor.fetchall():print(f"{row[0]}: ¥{row[1]}")# 3. UPDATE - 更新数据 cursor.execute("UPDATE products SET price = price * 0.9 WHERE category = ?", ('电子产品',) )print(f"\n折扣更新影响行数: {cursor.rowcount}")# 4. DELETE - 删除数据 cursor.execute("DELETE FROM products WHERE stock = 0")print(f"删除零库存产品影响行数: {cursor.rowcount}") conn.commit()# 运行示例basic_crud_operations()
2.2 高级查询技巧
defadvanced_query_techniques():"""高级查询技巧"""with sqlite3.connect('advanced.db') as conn: cursor = conn.cursor()# 创建示例数据 cursor.execute(''' CREATE TABLE IF NOT EXISTS orders ( id INTEGER PRIMARY KEY, customer_id INTEGER, amount REAL, status TEXT, order_date DATE ) ''') cursor.execute(''' CREATE TABLE IF NOT EXISTS customers ( id INTEGER PRIMARY KEY, name TEXT, email TEXT ) ''')# 插入示例数据 customers = [(1, '张三', 'zhangsan@email.com'), (2, '李四', 'lisi@email.com')] orders = [ (1, 1, 100.0, 'completed', '2024-01-15'), (2, 1, 200.0, 'pending', '2024-01-16'), (3, 2, 150.0, 'completed', '2024-01-14'), (4, 2, 300.0, 'completed', '2024-01-17') ] cursor.executemany("INSERT OR IGNORE INTO customers VALUES (?, ?, ?)", customers) cursor.executemany("INSERT OR IGNORE INTO orders VALUES (?, ?, ?, ?, ?)", orders)# 1. JOIN查询print("=== 客户订单信息 ===") cursor.execute(''' SELECT c.name, o.amount, o.status, o.order_date FROM customers c JOIN orders o ON c.id = o.customer_id ORDER BY o.order_date DESC ''')for row in cursor.fetchall():print(row)# 2. 聚合查询print("\n=== 订单统计 ===") cursor.execute(''' SELECT status, COUNT(*) as order_count, SUM(amount) as total_amount, AVG(amount) as avg_amount FROM orders GROUP BY status ''')for row in cursor.fetchall():print(f"状态: {row[0]}, 订单数: {row[1]}, 总金额: {row[2]:.2f}, 平均金额: {row[3]:.2f}")# 3. 子查询print("\n=== 高价值客户 ===") cursor.execute(''' SELECT name, email FROM customers WHERE id IN ( SELECT customer_id FROM orders GROUP BY customer_id HAVING SUM(amount) > 200 ) ''')for row in cursor.fetchall():print(row)# 4. 分页查询print("\n=== 订单分页 ===") page_size = 2 page_number = 1 offset = (page_number - 1) * page_size cursor.execute(''' SELECT * FROM orders ORDER BY order_date DESC LIMIT ? OFFSET ? ''', (page_size, offset))print(f"第{page_number}页订单:")for row in cursor.fetchall():print(row) conn.commit()# 运行示例advanced_query_techniques()
2.3 事务管理与性能优化
deftransaction_performance_demo():"""事务管理与性能优化"""with sqlite3.connect('performance.db') as conn: cursor = conn.cursor() cursor.execute(''' CREATE TABLE IF NOT EXISTS log_entries ( id INTEGER PRIMARY KEY, message TEXT, level TEXT, timestamp DATETIME DEFAULT CURRENT_TIMESTAMP ) ''')# 性能对比:单条插入 vs 批量插入import time# 单条插入(不使用事务) start_time = time.time()for i inrange(1000): cursor.execute("INSERT INTO log_entries (message, level) VALUES (?, ?)", (f"日志消息 {i}", "INFO") ) conn.commit() # 每次提交 single_time = time.time() - start_time# 清空表 cursor.execute("DELETE FROM log_entries") conn.commit()# 批量插入(使用事务) start_time = time.time()for i inrange(1000): cursor.execute("INSERT INTO log_entries (message, level) VALUES (?, ?)", (f"日志消息 {i}", "INFO") ) conn.commit() # 一次提交 batch_time = time.time() - start_timeprint(f"单条插入时间: {single_time:.3f}秒")print(f"批量插入时间: {batch_time:.3f}秒")print(f"性能提升: {single_time/batch_time:.1f}倍")# 使用executemany进一步优化 cursor.execute("DELETE FROM log_entries") conn.commit() start_time = time.time() log_data = [(f"消息{i}", "INFO") for i inrange(1000)] cursor.executemany("INSERT INTO log_entries (message, level) VALUES (?, ?)", log_data ) conn.commit() executemany_time = time.time() - start_timeprint(f"executemany时间: {executemany_time:.3f}秒")print(f"相比批量插入提升: {batch_time/executemany_time:.1f}倍")# 运行示例transaction_performance_demo()
三、ORM框架:SQLAlchemy实战
3.1 SQLAlchemy基础
from sqlalchemy import create_engine, Column, Integer, String, Float, DateTime, ForeignKeyfrom sqlalchemy.ext.declarative import declarative_basefrom sqlalchemy.orm import sessionmaker, relationshipfrom datetime import datetime# 定义基类Base = declarative_base()# 定义数据模型classUser(Base): __tablename__ = 'users'id = Column(Integer, primary_key=True) username = Column(String(50), unique=True, nullable=False) email = Column(String(100), unique=True, nullable=False) created_at = Column(DateTime, default=datetime.utcnow)# 关系 posts = relationship("Post", back_populates="author")def__repr__(self):returnf"<User(username='{self.username}', email='{self.email}')>"classPost(Base): __tablename__ = 'posts'id = Column(Integer, primary_key=True) title = Column(String(200), nullable=False) content = Column(String, nullable=False) author_id = Column(Integer, ForeignKey('users.id')) created_at = Column(DateTime, default=datetime.utcnow)# 关系 author = relationship("User", back_populates="posts")def__repr__(self):returnf"<Post(title='{self.title}', author_id={self.author_id})>"defsqlalchemy_basic_demo():"""SQLAlchemy基础示例"""# 创建引擎和会话 engine = create_engine('sqlite:///orm_demo.db', echo=True) # echo=True显示SQL Session = sessionmaker(bind=engine) session = Session()# 创建表 Base.metadata.create_all(engine)# 1. 创建数据 user1 = User(username='alice', email='alice@example.com') user2 = User(username='bob', email='bob@example.com') post1 = Post(title='第一篇帖子', content='这是Alice的帖子', author=user1) post2 = Post(title='第二篇帖子', content='这是Bob的帖子', author=user2) post3 = Post(title='第三篇帖子', content='Alice的另一篇帖子', author=user1)# 添加到会话并提交 session.add_all([user1, user2, post1, post2, post3]) session.commit()# 2. 查询数据print("=== 所有用户 ===") users = session.query(User).all()for user in users:print(user)print("\n=== 特定用户帖子 ===") alice = session.query(User).filter_by(username='alice').first()for post in alice.posts:print(f"{alice.username}的帖子: {post.title}")# 3. 更新数据 alice.email = 'alice_new@example.com' session.commit()print(f"\n更新后邮箱: {alice.email}")# 4. 删除数据 session.delete(post3) session.commit()print(f"删除帖子后,Alice帖子数量: {len(alice.posts)}") session.close()# 运行示例sqlalchemy_basic_demo()
3.2 高级查询与关系
defsqlalchemy_advanced_queries():"""SQLAlchemy高级查询""" engine = create_engine('sqlite:///orm_demo.db') Session = sessionmaker(bind=engine) session = Session()# 1. 复杂查询print("=== 复杂查询示例 ===")# 连接查询 results = session.query(User.username, Post.title).\ join(Post).\filter(User.username == 'alice').\all()for username, title in results:print(f"{username}: {title}")# 聚合查询from sqlalchemy import func user_post_count = session.query( User.username, func.count(Post.id).label('post_count') ).join(Post).group_by(User.id).all()print("\n=== 用户帖子统计 ===")for username, count in user_post_count:print(f"{username}: {count}篇帖子")# 2. 分页查询print("\n=== 分页查询 ===") page_size = 2 page = 1 posts = session.query(Post).\ order_by(Post.created_at.desc()).\ limit(page_size).\ offset((page - 1) * page_size).\all()for post in posts:print(f"{post.title} - {post.created_at}")# 3. 事务处理print("\n=== 事务处理 ===")try:# 开始事务 new_user = User(username='charlie', email='charlie@example.com') session.add(new_user) new_post = Post(title='新帖子', content='测试内容', author=new_user) session.add(new_post)# 模拟错误ifTrue: # 改为False测试正常提交raise ValueError("模拟事务失败") session.commit()print("事务提交成功")except Exception as e: session.rollback()print(f"事务回滚: {e}") session.close()# 运行示例sqlalchemy_advanced_queries()
四、NoSQL数据库:MongoDB与Redis
4.1 MongoDB集成
from pymongo import MongoClientfrom bson import ObjectIdimport datetimedefmongodb_demo():"""MongoDB示例"""# 连接MongoDB client = MongoClient('mongodb://localhost:27017/') db = client['test_database'] collection = db['users']# 1. 插入文档 user_data = {'username': 'john_doe','email': 'john@example.com','age': 30,'interests': ['编程', '音乐', '旅行'],'created_at': datetime.datetime.utcnow() } result = collection.insert_one(user_data)print(f"插入文档ID: {result.inserted_id}")# 2. 查询文档print("\n=== 查询所有用户 ===")for user in collection.find():print(user)print("\n=== 条件查询 ===") john = collection.find_one({'username': 'john_doe'})print(f"找到用户: {john}")# 3. 更新文档 update_result = collection.update_one( {'username': 'john_doe'}, {'$set': {'age': 31, 'updated_at': datetime.datetime.utcnow()}} )print(f"更新影响文档数: {update_result.modified_count}")# 4. 聚合查询print("\n=== 聚合查询 ===") pipeline = [ {'$group': {'_id': None, 'average_age': {'$avg': '$age'}}} ] aggregation_result = list(collection.aggregate(pipeline))if aggregation_result:print(f"平均年龄: {aggregation_result[0]['average_age']}")# 5. 索引管理 collection.create_index('username', unique=True)print("已创建用户名唯一索引")# 清理 collection.delete_many({}) client.close()# 运行示例(需要MongoDB服务)# mongodb_demo()
4.2 Redis缓存与消息队列
import redisimport jsondefredis_demo():"""Redis示例"""# 连接Redis r = redis.Redis(host='localhost', port=6379, db=0, decode_responses=True)# 1. 字符串操作 r.set('user:1:name', '张三') r.set('user:1:email', 'zhangsan@example.com') r.setex('temp:session', 3600, 'session_data') # 带过期时间print(f"用户姓名: {r.get('user:1:name')}")print(f"Session剩余时间: {r.ttl('temp:session')}秒")# 2. 哈希操作 user_data = {'name': '李四','email': 'lisi@example.com','age': '25' } r.hset('user:2', mapping=user_data)print(f"用户2信息: {r.hgetall('user:2')}")# 3. 列表操作(消息队列)# 生产者for i inrange(5): message = json.dumps({'id': i, 'content': f'消息{i}'}) r.lpush('message_queue', message)# 消费者print("\n=== 处理消息 ===")whileTrue: message = r.rpop('message_queue')ifnot message:break data = json.loads(message)print(f"处理消息: {data}")# 4. 集合操作 r.sadd('online_users', 'user1', 'user2', 'user3')print(f"在线用户: {r.smembers('online_users')}")# 5. 发布订阅defmessage_handler(message):print(f"收到消息: {message['data']}") pubsub = r.pubsub() pubsub.subscribe('news_channel')# 在另一个线程中发布消息import threadingdefpublisher():import time time.sleep(0.1) r.publish('news_channel', '最新新闻!') threading.Thread(target=publisher).start()# 接收消息 message = pubsub.get_message(timeout=1)if message:print(f"频道消息: {message}")# 清理 r.flushdb()print("Redis数据已清理")# 运行示例(需要Redis服务)# redis_demo()
五、异步数据库操作
5.1 异步SQLAlchemy
import asynciofrom sqlalchemy.ext.asyncio import create_async_engine, AsyncSessionfrom sqlalchemy.orm import sessionmakerfrom sqlalchemy import selectasyncdefasync_sqlalchemy_demo():"""异步SQLAlchemy示例"""# 创建异步引擎(使用aiosqlite) engine = create_async_engine('sqlite+aiosqlite:///async_demo.db', echo=True )asyncwith engine.begin() as conn:await conn.run_sync(Base.metadata.create_all)# 创建异步会话 AsyncSessionLocal = sessionmaker( engine, class_=AsyncSession, expire_on_commit=False )asyncwith AsyncSessionLocal() as session:# 异步插入 new_user = User(username='async_user', email='async@example.com') session.add(new_user)await session.commit()# 异步查询 result = await session.execute( select(User).where(User.username == 'async_user') ) user = result.scalar_one()print(f"异步查询结果: {user}")# 异步更新 user.email = 'updated_async@example.com'await session.commit()# 验证更新 result = await session.execute( select(User).where(User.username == 'async_user') ) updated_user = result.scalar_one()print(f"更新后邮箱: {updated_user.email}")await engine.dispose()# 运行异步示例asyncio.run(async_sqlalchemy_demo())
5.2 异步MongoDB
import motor.motor_asynciofrom bson import ObjectIdasyncdefasync_mongodb_demo():"""异步MongoDB示例"""# 连接异步MongoDB客户端 client = motor.motor_asyncio.AsyncIOMotorClient('mongodb://localhost:27017/') db = client['async_database'] collection = db['users']# 异步插入 user_data = {'username': 'async_user','email': 'async@example.com','created_at': datetime.datetime.utcnow() } result = await collection.insert_one(user_data)print(f"插入文档ID: {result.inserted_id}")# 异步查询 user = await collection.find_one({'username': 'async_user'})print(f"查询结果: {user}")# 异步更新await collection.update_one( {'username': 'async_user'}, {'$set': {'updated_at': datetime.datetime.utcnow()}} )# 异步聚合 pipeline = [{'$group': {'_id': None, 'count': {'$sum': 1}}}] cursor = collection.aggregate(pipeline)asyncfor result in cursor:print(f"文档总数: {result['count']}")# 清理await collection.delete_many({}) client.close()# 运行示例asyncio.run(async_mongodb_demo())
六、数据库迁移与版本控制
6.1 Alembic数据库迁移
# alembic_demo.pyfrom alembic import commandfrom alembic.config import Configimport osdefalembic_migration_demo():"""Alembic数据库迁移示例"""# 初始化Alembic配置 alembic_cfg = Config("alembic.ini")# 1. 初始化迁移环境(首次运行)ifnot os.path.exists("alembic"): command.init(alembic_cfg, "alembic")print("Alembic初始化完成")# 2. 创建新的迁移脚本 command.revision(alembic_cfg, autogenerate=True, message="添加新字段")print("迁移脚本已创建")# 3. 执行迁移 command.upgrade(alembic_cfg, "head")print("数据库迁移完成")# 4. 查看迁移历史 command.history(alembic_cfg)# 5. 回滚迁移# command.downgrade(alembic_cfg, "-1")# print("回滚到上一个版本")# 运行示例(需要先配置alembic.ini)# alembic_migration_demo()
6.2 手动迁移方案
defmanual_migration_demo():"""手动数据库迁移示例"""with sqlite3.connect('migration_demo.db') as conn: cursor = conn.cursor()# 初始表结构 cursor.execute(''' CREATE TABLE IF NOT EXISTS products ( id INTEGER PRIMARY KEY, name TEXT NOT NULL, price REAL NOT NULL ) ''')# 模拟数据 cursor.execute("INSERT INTO products (name, price) VALUES ('产品1', 100.0)") conn.commit()# 迁移:添加新字段try: cursor.execute("ALTER TABLE products ADD COLUMN description TEXT")print("迁移成功:添加description字段")except sqlite3.OperationalError as e:print(f"字段已存在或其它错误: {e}")# 迁移:添加索引try: cursor.execute("CREATE INDEX idx_products_name ON products(name)")print("迁移成功:创建名称索引")except sqlite3.OperationalError as e:print(f"索引已存在或其它错误: {e}")# 验证迁移 cursor.execute("PRAGMA table_info(products)") columns = [row[1] for row in cursor.fetchall()]print(f"表结构: {columns}")# 数据迁移示例try: cursor.execute("UPDATE products SET description = '默认描述' WHERE description IS NULL")print(f"数据迁移影响行数: {cursor.rowcount}")except sqlite3.OperationalError as e:print(f"数据迁移错误: {e}") conn.commit()# 运行示例manual_migration_demo()
七、性能优化与监控
7.1 数据库性能优化
defdatabase_performance_optimization():"""数据库性能优化示例"""with sqlite3.connect('performance_opt.db') as conn: cursor = conn.cursor()# 创建测试表 cursor.execute(''' CREATE TABLE IF NOT EXISTS performance_test ( id INTEGER PRIMARY KEY, name TEXT, value INTEGER, category TEXT, created_date DATE ) ''')# 插入测试数据import random test_data = []for i inrange(10000): category = random.choice(['A', 'B', 'C', 'D']) value = random.randint(1, 1000) date = f"2024-01-{random.randint(1, 28):02d}" test_data.append((f"Item_{i}", value, category, date)) cursor.executemany("INSERT INTO performance_test (name, value, category, created_date) VALUES (?, ?, ?, ?)", test_data ) conn.commit()# 1. 索引优化前import time start_time = time.time() cursor.execute("SELECT * FROM performance_test WHERE category = 'A'") results = cursor.fetchall() no_index_time = time.time() - start_timeprint(f"无索引查询时间: {no_index_time:.4f}秒, 结果数: {len(results)}")# 2. 创建索引 cursor.execute("CREATE INDEX idx_category ON performance_test(category)") cursor.execute("CREATE INDEX idx_date ON performance_test(created_date)")# 3. 索引优化后 start_time = time.time() cursor.execute("SELECT * FROM performance_test WHERE category = 'A'") results = cursor.fetchall() with_index_time = time.time() - start_timeprint(f"有索引查询时间: {with_index_time:.4f}秒, 结果数: {len(results)}")print(f"性能提升: {no_index_time/with_index_time:.1f}倍")# 4. 查询优化技巧print("\n=== 查询优化技巧 ===")# 使用EXPLAIN分析查询计划 cursor.execute("EXPLAIN QUERY PLAN SELECT * FROM performance_test WHERE category = 'A'") explain_result = cursor.fetchall()print("查询计划分析:")for row in explain_result:print(f" {row[3]}")# 避免SELECT * start_time = time.time() cursor.execute("SELECT name, value FROM performance_test WHERE category = 'A'") specific_columns_time = time.time() - start_timeprint(f"特定列查询时间: {specific_columns_time:.4f}秒")# 使用LIMIT start_time = time.time() cursor.execute("SELECT * FROM performance_test WHERE category = 'A' LIMIT 100") with_limit_time = time.time() - start_timeprint(f"带LIMIT查询时间: {with_limit_time:.4f}秒") conn.commit()# 运行示例database_performance_optimization()
7.2 数据库监控与诊断
defdatabase_monitoring_demo():"""数据库监控示例"""with sqlite3.connect('monitoring.db') as conn: cursor = conn.cursor()# 1. 获取数据库信息 cursor.execute("PRAGMA database_list") databases = cursor.fetchall()print("=== 数据库信息 ===")for db in databases:print(f"数据库: {db[1]}, 文件: {db[2]}")# 2. 获取表信息 cursor.execute("SELECT name FROM sqlite_master WHERE type='table'") tables = cursor.fetchall()print("\n=== 表信息 ===")for table in tables:print(f"表: {table[0]}")# 3. 索引信息 cursor.execute("PRAGMA index_list('performance_test')") indexes = cursor.fetchall()print("\n=== 索引信息 ===")for index in indexes:print(f"索引: {index[1]}, 唯一: {index[2]}")# 4. 性能统计 cursor.execute("PRAGMA stats") stats = cursor.fetchall()print("\n=== 统计信息 ===")for stat in stats:print(f"{stat[0]}: {stat[1]}")# 5. 连接状态print(f"\n=== 连接状态 ===")print(f"连接已打开: {conn.isolation_level isnotNone}")# 6. 内存使用 cursor.execute("PRAGMA page_count") page_count = cursor.fetchone()[0] cursor.execute("PRAGMA page_size") page_size = cursor.fetchone()[0] total_size = page_count * page_sizeprint(f"数据库大小: {total_size / 1024:.2f} KB")# 运行示例database_monitoring_demo()
八、安全最佳实践
8.1 SQL注入防护
defsql_injection_prevention():"""SQL注入防护示例"""with sqlite3.connect('security.db') as conn: cursor = conn.cursor() cursor.execute(''' CREATE TABLE IF NOT EXISTS users ( id INTEGER PRIMARY KEY, username TEXT UNIQUE, password TEXT ) ''') cursor.execute("INSERT OR IGNORE INTO users VALUES (1, 'admin', 'secret')") conn.commit()# 1. 危险的字符串拼接(易受SQL注入)defunsafe_login(username, password): query = f"SELECT * FROM users WHERE username = '{username}' AND password = '{password}'" cursor.execute(query)return cursor.fetchone() isnotNone# 2. 安全的参数化查询defsafe_login(username, password): cursor.execute("SELECT * FROM users WHERE username = ? AND password = ?", (username, password) )return cursor.fetchone() isnotNone# 测试SQL注入print("=== SQL注入测试 ===")# 正常登录print("正常登录:", safe_login('admin', 'secret'))# SQL注入攻击 malicious_password = "' OR '1'='1"print("SQL注入攻击尝试:")# 不安全方式try: result = unsafe_login('admin', malicious_password)print(f"不安全方式结果: {result} (安全漏洞!)")except Exception as e:print(f"不安全方式错误: {e}")# 安全方式 result = safe_login('admin', malicious_password)print(f"安全方式结果: {result} (安全)")# 3. 输入验证defvalidate_input(username, password):"""输入验证"""ifnotisinstance(username, str) ornotisinstance(password, str):returnFalseiflen(username) > 50orlen(password) > 100:returnFalse# 更多验证逻辑...returnTruedefsecure_login(username, password):"""安全的登录函数"""ifnot validate_input(username, password):returnFalsereturn safe_login(username, password)print(f"安全登录验证: {secure_login('admin', 'secret')}")# 运行示例sql_injection_prevention()
8.2 连接安全与加密
defconnection_security_demo():"""数据库连接安全示例"""import ssl# MySQL SSL连接示例try:# 创建SSL上下文 ssl_context = ssl.create_default_context() ssl_context.check_hostname = False ssl_context.verify_mode = ssl.CERT_NONE conn = mysql.connector.connect( host='localhost', user='your_username', password='your_password', database='test_db', ssl_ca='/path/to/ca-cert.pem', ssl_cert='/path/to/client-cert.pem', ssl_key='/path/to/client-key.pem', ssl_disabled=False )print("SSL连接成功") conn.close()except mysql.connector.Error as e:print(f"SSL连接错误: {e}")# 连接字符串安全defsecure_connection_string():"""安全的连接字符串处理"""import osfrom urllib.parse import quote_plus# 从环境变量获取敏感信息 db_host = os.getenv('DB_HOST', 'localhost') db_user = os.getenv('DB_USER', 'username') db_pass = os.getenv('DB_PASS', 'password') db_name = os.getenv('DB_NAME', 'database')# 安全构建连接字符串 encoded_password = quote_plus(db_pass) connection_string = f"mysql://{db_user}:{encoded_password}@{db_host}/{db_name}"return connection_stringprint(f"安全连接字符串: {secure_connection_string()}")# 运行示例(需要配置SSL证书)# connection_security_demo()
九、总结:数据库技术选型指南
数据库类型 | 适用场景 | Python库推荐 | 优点 |
|---|---|---|---|
SQLite | 轻量级应用、嵌入式、测试 | sqlite3 | 零配置、文件式、简单 |
MySQL | Web应用、事务处理 | mysql-connector | 成熟、功能丰富、社区支持好 |
PostgreSQL | 复杂应用、地理数据 | psycopg2 | 高级功能、JSON支持、ACID兼容 |
MongoDB | 文档存储、灵活模式 | pymongo | 灵活、易扩展、JSON原生 |
Redis | 缓存、消息队列、会话存储 | redis | 高速、内存存储、多功能 |
Elasticsearch | 搜索、日志分析 | elasticsearch | 全文搜索、分布式、可扩展 |
选择建议:
🟢 简单应用:SQLite
🟡 Web应用:MySQL/PostgreSQL
🔵 灵活数据:MongoDB
🔴 高性能缓存:Redis
🟣 搜索需求:Elasticsearch
互动话题:你在项目中使用过哪些数据库?遇到过什么有趣的问题或挑战?欢迎在评论区分享你的数据库使用经验!
长按或扫描下方二维码,免费获取 Python公开课和大佬打包整理的几百G的学习资料,内容包含但不限于Python电子书、教程、项目接单、源码等等 推荐阅读
Python+PostgreSQL数据库交互详解:从基础连接到高级ORM
点击 阅读原文 了解更多