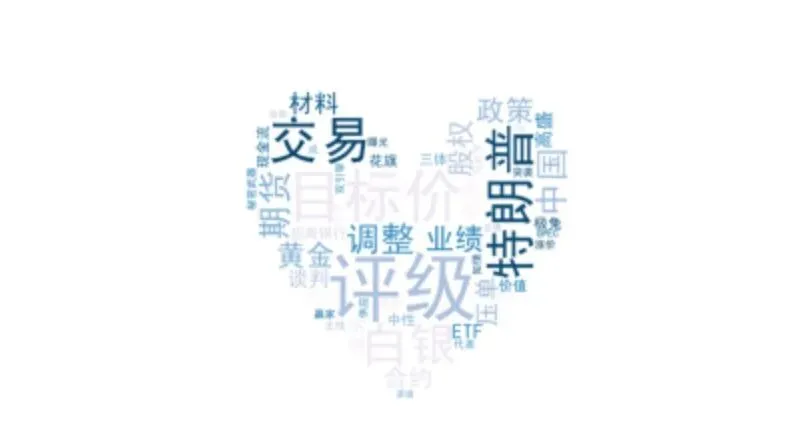
import jieba.posseg as psegimport matplotlib.pyplot as pltfrom os import pathimport reimport requestsfrom PIL import Image#图像处理库import numpy as npfrom wordcloud import WordCloudplt.style.use("ggplot")def fetch_sina_news(): # PATTERN = re.compile('.shtml" target="_blank">(.*?)</a><span>(.*?)</span></li>')#提取摘要 PATTERN = re.compile('"title":(.*?),')#提取标题 # BASE_URL = "http://roll.news.sina.com.cn/news/gnxw/gdxw1/index_" #提取数据的API接口 BASE_URL = 'https://feed.mix.sina.com.cn/api/roll/get?pageid=153&lid=2509&k=&num=50&page=1&r=0.8649260052895962&callback=jQuery1112045860870699715606_1700536939737&_=1700536939738' # MAX_PAGE_NUM = 10 with open('subjects.txt', 'w', encoding='utf-8') as f: #for i in range(1, MAX_PAGE_NUM): #print('Downloading page #{}'.format(i)) # r = requests.get(BASE_URL + str(i)+'.shtml') r = requests.get(BASE_URL) # r.encoding='gb2312' # data = r.text data = r.text.encode('utf-8').decode('raw-unicode-escape')#解决编码问题 p = re.findall(PATTERN, data) for s in p: # f.write(s[0]) f.write(s) # time.sleep(5)def extract_words(): with open('subjects.txt', 'r', encoding='utf-8') as f: news_subjects = f.readlines() #用集合推导式生成停用词集合,推导式参数:元素for元素in序列if条件 #line.strip()可以跳过每行首位的空白字符 stop_words = set(line.strip() for line in open('stopwords.txt', encoding='utf-8')) newslist = [] for subject in news_subjects: if subject.isspace(): continue#跳过空行 # segment words line by line p = re.compile( "n[a-z0-9]{0,2}") # n, nr, ns, ... are the flags of nouns,编译成一个正则对象,n表示名词 word_list = pseg.cut(subject)#分词+词性标注,返回词语和词性(名词、动词等) for word, flag in word_list: if word not in stop_words and p.search(flag) != None:#不在停用词表里且有词性标注(是个词儿) newslist.append(word) # Using Counter function to compute word frequency # from collections import Counter;词频统计方法1 # content = Counter(newslist) # Manually compute word frequency content = {} for item in newslist: content[item] = content.get(item, 0) + 1#计算词频方法2,第一次出现就取0 #d = path.dirname(__file__) mask_image = np.array(Image.open(('love.jpg')))#需要数组存图像像素信息 Wc = WordCloud( font_path='simhei.ttf', background_color='white', # color of background mask=mask_image, colormap='PuBu', # the color map of words max_words=50)#词云图参数设置 wordcloud = Wc.generate_from_frequencies(content)#从这里获取词频 # Display the generated image: plt.imshow(wordcloud)#渲染出来 plt.axis("off")#隐藏坐标轴和刻度 wordcloud.to_file('wordcloud.jpg') # Or save the map with plt.savefig to control the image dpi # plt.savefig('wordcloud.jpg', dpi=200) plt.show()#显示当前绘制的图像if __name__ == "__main__": fetch_sina_news() extract_words()


 10个月宝宝每天需要喝多少奶粉?