还在手写requests循环?还在被反爬折磨得焦头烂额? 本文带你全面掌握Python爬虫框架,从原理到实战,从单机到分布式。 读完这一篇,你的爬虫能力将提升一个维度。写在前面
爬虫,作为数据采集的核心手段,在数据分析、机器学习、市场监控等领域扮演着不可替代的角色。而框架的出现,让我们从“造轮子”转向“搭积木”——你只需要关注数据从哪里来、怎么解析,剩下的请求调度、并发控制、错误重试、数据去重……框架全包了。
为什么需要框架?
裸写爬虫的痛点 | 框架提供的解决方案 |
手动管理请求队列 | 内置调度器 + 优先级队列 |
需要自己实现并发 | 异步/多线程引擎,自动调节并发度 |
异常处理繁琐 | 中间件 + 自动重试 + 错误日志 |
数据存储混乱 | 标准Item Pipeline,支持多输出 |
重复URL无法去重 | 布隆过滤器 / 集合去重,默认支持 |
难以扩展分布式 | 基于Redis的分布式组件 |
一、Python爬虫框架全景图
目前最主流的Python爬虫框架/库可以分成五类:
类别 | 代表 | 特点 |
🏭 全能型框架 | Scrapy | 工业标准,功能最全 |
⚡ 轻量型组合 | Requests + BeautifulSoup | 灵活,适合小任务 |
🎬 动态渲染专用 | Selenium / Playwright | 模拟浏览器,处理JS |
🚀 异步高性能 | aiohttp / httpx | 高并发API采集 |
🖱️ 可视化/低代码 | Portia / Crawley | 点选式,无需编程 |
下面逐一深入拆解。
二、Scrapy —— 真正的爬虫之王
2.1 为什么Scrapy如此强大?
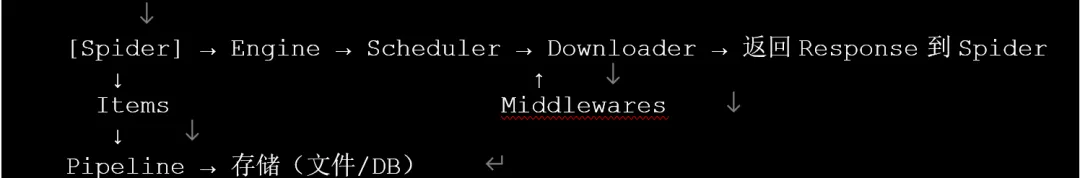
Scrapy是一个基于Twisted异步网络框架的爬虫框架,其核心设计遵循“管道-过滤器”架构。
架构简图:
六大核心组件:
组件 | 职责 | 常见扩展 |
Engine | 控制数据流、触发事件 | 几乎不直接修改 |
Scheduler | 管理URL队列,去重 | 替换为Redis持久化队列 |
Downloader | 下载网页,处理HTTP | 配置代理、SSL、重试 |
Spiders | 解析Response,提取Item | 用户核心编码区 |
Item Pipeline | 清洗、验证、存储Item | 写入DB、去重、过滤 |
Middlewares | 请求/响应拦截 | 添加Header、代理、模拟登录 |
2.2 实战:从零搭建一个Scrapy项目
scrapy startproject tutorialcd tutorialscrapy genspider quotes quotes.toscrape.com
编写spider (quotes.py):
import scrapyfrom tutorial.items import QuoteItemclass QuotesSpider(scrapy.Spider):name = "quotes"allowed_domains = ["quotes.toscrape.com"]start_urls = ['http://quotes.toscrape.com/']def parse(self, response):for quote in response.css('div.quote'):item = QuoteItem()item['text'] = quote.css('span.text::text').get()item['author'] = quote.css('small.author::text').get()item['tags'] = quote.css('div.tags a.tag::text').getall()yield item# 翻页next_page = response.css('li.next a::attr(href)').get()if next_page:yield response.follow(next_page, self.parse)
定义Item (items.py):
import scrapyclass QuoteItem(scrapy.Item):text = scrapy.Field()author = scrapy.Field()tags = scrapy.Field()
编写Pipeline (pipelines.py) 存储到JSON:
import jsonclass JsonWriterPipeline:def open_spider(self, spider):self.file = open('quotes.json', 'w', encoding='utf-8')self.file.write('[\n')def process_item(self, item, spider):line = json.dumps(dict(item), ensure_ascii=False) + ',\n'self.file.write(line)return itemdef close_spider(self, spider):self.file.seek(self.file.tell() - 2)self.file.write('\n]')self.file.close()
启用Pipeline (settings.py):
ITEM_PIPELINES = {'tutorial.pipelines.JsonWriterPipeline': 300,}
运行:
scrapy crawl quotes -o output.json
2.3 深入中间件:反爬与代理
随机User-Agent中间件:
import randomfrom fake_useragent import UserAgentclass RandomUserAgentMiddleware:def __init__(self):self.ua = UserAgent()def process_request(self, request, spider):request.headers.setdefault('User-Agent', self.ua.random)
代理中间件:
class ProxyMiddleware:def process_request(self, request, spider):request.meta['proxy'] = 'http://your-proxy-ip:port'
下载延迟与自动限速 (settings.py):
DOWNLOAD_DELAY = 1.5AUTOTHROTTLE_ENABLED = TrueAUTOTHROTTLE_START_DELAY = 1.0AUTOTHROTTLE_MAX_DELAY = 10.0CONCURRENT_REQUESTS_PER_DOMAIN = 8
2.4 分布式爬虫:Scrapy-Redis
单机Scrapy受限于内存队列,无法跨机器。Scrapy-Redis将调度器和去重集迁移到Redis。
安装:pip install scrapy-redis
配置 (settings.py):
SCHEDULER = "scrapy_redis.scheduler.Scheduler"DUPEFILTER_CLASS = "scrapy_redis.dupefilter.RFPDupeFilter"REDIS_HOST = '192.168.1.100'REDIS_PORT = 6379SCHEDULER_PERSIST = True
Spider继承RedisSpider:
from scrapy_redis.spiders import RedisSpiderclass MySpider(RedisSpider):name = 'myspider'redis_key = 'myspider:start_urls'
运行后,在Redis中LPUSH myspider:start_urls http://...即可。
2.5 Scrapy性能调优建议
●CONCURRENT_REQUESTS:默认16,可调至100+(视目标网站而定)
●COOKIES_ENABLED = False:减少内存占用
●DNSCACHE_ENABLED = True:DNS缓存
●使用HTTP/2:DOWNLOAD_HANDLERS = {'http': 'scrapy.core.downloader.handlers.http2.H2DownloadHandler'}
●LOG_LEVEL = 'ERROR':减少日志输出
三、轻量级组合:Requests + BeautifulSoup
当任务很小、无需工程化时,这是最灵活的选择。
基础模板
import requestsfrom bs4 import BeautifulSoupfrom concurrent.futures import ThreadPoolExecutordef fetch(url):try:resp = requests.get(url, timeout=10, headers={'User-Agent': 'Mozilla/5.0'})resp.raise_for_status()soup = BeautifulSoup(resp.text, 'lxml')title = soup.find('title').get_text()return {'url': url, 'title': title}except Exception as e:print(f"Error {url}: {e}")urls = [f'http://example.com/page/{i}' for i in range(1, 101)]with ThreadPoolExecutor(max_workers=10) as executor:results = list(executor.map(fetch, urls))
会话保持与重试
session = requests.Session()session.headers.update({'User-Agent': '...'})adapter = requests.adapters.HTTPAdapter(max_retries=3)session.mount('http://', adapter)session.mount('https://', adapter)
性能瓶颈
●同步阻塞,即使使用线程池,GIL仍限制计算密集型解析。
●无内置去重、调度、监控。适合<1万URL的临时任务。
四、动态页面爬取:Selenium / Playwright / Pyppeteer
现代网站大量使用JavaScript渲染,直接请求HTML拿不到内容。需要用浏览器自动化框架。
4.1 Selenium(最成熟)
from selenium import webdriverfrom selenium.webdriver.common.by import Byfrom selenium.webdriver.chrome.options import Optionsoptions = Options()options.add_argument('--headless')driver = webdriver.Chrome(options=options)driver.get('https://example.com')# 等待元素出现from selenium.webdriver.support.ui import WebDriverWaitfrom selenium.webdriver.support import expected_conditions as ECWebDriverWait(driver, 10).until(EC.presence_of_element_located((By.ID, 'content')))html = driver.page_sourcedriver.quit()
4.2 Playwright(新一代)
微软出品,API更现代,自动等待,性能更好。
from playwright.sync_api import sync_playwrightwith sync_playwright() as p:browser = p.chromium.launch(headless=True)page = browser.new_page()page.goto('https://example.com')page.wait_for_selector('.content')content = page.content()browser.close()
异步版本性能极高,适合大规模渲染。
4.3 框架对比
框架 | 速度 | 资源占用 | 异步支持 | 生态 |
Selenium | 较慢 | 高 | 有限 | 最丰富 |
Playwright | 中快 | 中 | 原生支持 | 增长中 |
Pyppeteer | 快 | 中 | 全异步 | 中等 |
五、异步HTTP框架:aiohttp / httpx
对于API爬取、纯静态页面,使用异步HTTP客户端可以获得比Scrapy更高的吞吐量。
aiohttp示例
import aiohttpimport asynciofrom asyncio import Semaphoresem = Semaphore(50)async def fetch(session, url):async with sem:async with session.get(url, ssl=False) as resp:return await resp.text()async def main():urls = [f'https://api.example.com/data/{i}' for i in range(1000)]async with aiohttp.ClientSession(headers={'User-Agent': 'Mozilla/5.0'}) as session:tasks = [fetch(session, url) for url in urls]results = await asyncio.gather(*tasks)asyncio.run(main())
适用场景:高并发的API采集、实时数据监控。 注意:需要自己实现重试、代理轮换等。
六、反爬虫深度对抗策略
6.1 请求指纹与去重
Scrapy默认去重基于request_fingerprint(URL、Method、Body)。 自定义指纹:忽略某些参数,绕过顺序检测。
6.2 代理IP池实现
class RedisProxyMiddleware:def process_request(self, request, spider):proxy = redis_client.srandmember('proxies')request.meta['proxy'] = f'http://{proxy}'
6.3 验证码处理
●OCR:ddddocr 识别简单数字验证码
●第三方打码:超级鹰、图鉴
●滑块模拟:用Playwright模拟鼠标轨迹
6.4 字体反爬(猫眼、大众点评等)
网站将数字映射到自定义字体文件。 解法:下载.woff文件,用fontTools解析映射关系。
七、增量爬取与去重优化
方案一:基于时间戳在Item中记录crawled_at,Pipeline中检查数据库是否有更新的数据。
方案二:BloomFilter去重(适合海量URL,内存极小)
from pybloom_live import ScalableBloomFilterbloom = ScalableBloomFilter(initial_capacity=100000, error_rate=0.001)def is_duplicate(url):if url in bloom:return Truebloom.add(url)return False
在Scrapy中自定义DupeFilter,替代默认去重器。
八、爬虫部署与监控
8.1 Scrapyd + Scrapyd-Client
安装scrapyd,启动服务(默认6800端口)。 部署:scrapyd-deploy default -p myproject调度:curl http://localhost:6800/schedule.json -d project=myproject -d spider=quotes
8.2 Docker容器化
FROM python:3.9-slimWORKDIR /appCOPY requirements.txt .RUN pip install -r requirements.txtCOPY . .CMD ["scrapy", "crawl", "quotes"]
配合Kubernetes可实现弹性伸缩。
8.3 日志与告警
●使用logging模块记录错误,发送到钉钉/Slack。
●Scrapy内置Stats Collector,可监控请求量、响应码分布。
九、实战:电商商品爬虫(含动态加载)
场景:商品列表通过Ajax加载,详情页需要JS渲染,有简单反爬。
技术栈:Scrapy + Playwright(通过scrapy-playwright中间件)
安装:pip install scrapy-playwright
配置 (settings.py):
DOWNLOAD_HANDLERS = {"http": "scrapy_playwright.handler.ScrapyPlaywrightDownloadHandler","https": "scrapy_playwright.handler.ScrapyPlaywrightDownloadHandler",}TWISTED_REACTOR = "twisted.internet.asyncioreactor.AsyncioSelectorReactor"PLAYWRIGHT_BROWSER_TYPE = "chromium"
Spider代码:
import scrapyfrom scrapy_playwright.page import PageMethodclass ProductSpider(scrapy.Spider):name = "product"start_urls = ["https://example-shop.com/category/phones"]async def parse(self, response):page = response.meta["playwright_page"]# 点击“加载更多”直到无新数据while True:try:await page.click("button.load-more", timeout=5000)await page.wait_for_selector(".product-item", state="attached")except:breakcontent = await page.content()from parsel import Selectorsel = Selector(text=content)for product in sel.css(".product-item"):yield {"name": product.css(".name::text").get(),"price": product.css(".price::text").get(),"detail_url": product.css("a::attr(href)").get()}
十、框架选型终极指南
场景 | 首选 | 备选 | 理由 |
海量静态页面采集 | Scrapy | aiohttp+自研 | 工程化与扩展性 |
小规模、临时需求 | requests+bs4 | httpx+lxml | 轻量快速 |
登录态、JS渲染 | Playwright | Selenium | 更快且现代 |
高并发API采集 | aiohttp/httpx | Scrapy+自定义 | 原生异步性能极致 |
分布式大规模 | Scrapy-Redis | Nutch(Python不建议) | 生态成熟 |
非技术人员 | Portia / Web scraper | 八爪鱼 | 可视化点选 |
十一、未来趋势与避坑指南
趋势
●无代码爬虫平台(如Bright Data)将蚕食部分市场,但定制化仍需代码。
●AI辅助解析:利用GPT自动识别列表页、详情页字段。
●隐私合规:GDPR、中国《个人信息保护法》要求爬虫注意数据来源合法性。
●反爬升级:设备指纹、TLS指纹、JA3指纹,需要更底层的模拟(如curl_cffi)。
避坑指南
●遵守robots.txt,尊重网站意愿。
●控制请求速率,避免被封IP甚至起诉。
●数据用途:不可用于商业竞争、用户画像未经授权。
●验证码服务成本提前评估。
●动态页面慎用Selenium:一个浏览器实例占几百兆内存,50并发需要强大服务器。
十二、爬虫合规指南(重要!)
技术是中立的,但使用技术的人必须遵守法律与道德。 在编写和运行爬虫之前,请务必遵循以下规则:
1. 遵守 robots.txt
每个网站根目录下通常有robots.txt文件,规定了哪些路径允许爬取、哪些不允许。 示例:https://example.com/robots.txtPython中可使用urllib.robotparser解析:
from urllib.robotparser import RobotFileParserrp = RobotFileParser()rp.set_url("https://example.com/robots.txt")rp.read()can_fetch = rp.can_fetch("MyBot", "https://example.com/some/page")
2. 尊重版权与隐私
●个人数据(姓名、电话、地址等)未经授权不得采集。
●受版权保护的内容(文章、图片、音视频)不得用于商业用途。
●遵守 GDPR(欧盟通用数据保护条例)和 中国《个人信息保护法》。
3. 控制请求频率
●设置合理的DOWNLOAD_DELAY或CONCURRENT_REQUESTS,避免对目标服务器造成压力(类似DoS攻击)。
●建议模拟人类行为:随机间隔、随机User-Agent。
4. 声明身份
在请求头中设置合法的User-Agent,并可以添加From或Contact字段,表明爬虫身份和联系方式。
headers = {'User-Agent': 'MyBot/1.0 (+http://mysite.com/bot.html)','From': 'admin@mysite.com'}
5. 法律风险提示
●绕过反爬措施(如验证码、IP封锁)可能违反《计算机信息系统安全保护条例》或《反不正当竞争法》。
●未经许可爬取电商价格、竞品数据可能构成不正当竞争。
●国内已有多个因恶意爬虫被判刑的案例(如“车来了”爬取“酷米客”数据案)。
6. 最佳实践总结
✅ 可以做的:
●公开数据的非商业研究
●遵循robots.txt,礼貌爬取
●爬取前阅读网站的“服务条款”
❌ 不要做的:
●高频率请求导致网站瘫痪
●绕过登录、验证码等保护措施
●采集用户隐私或受版权保护的内容
●将爬取数据用于黑产、诈骗、不正当竞争
写在最后
爬虫框架的世界非常广阔,从简单的Requests到工业级的Scrapy,从同步到异步,从单机到分布式,每一步都有不同的挑战。
核心建议:
●初学者:花一周时间吃透Scrapy官方教程,胜过三个月零散写脚本。
●遇到反爬:先尝试降低速度、更换UA,再考虑代理、浏览器渲染。
●生产环境:务必做好日志、监控、队列持久化,否则半夜爬虫停了都不知道。
希望这份超详细的解读,能帮你建立起爬虫框架的完整知识体系。 如果觉得有用,欢迎点赞、在看、转发,让更多人少走弯路!
最后再次强调:技术无罪,但请合法合规地使用爬虫。采集数据前查看robots.txt,尊重版权和隐私。
参考资源:
●Scrapy官方文档
●Playwright Python
●Scrapy-Redis GitHub
●免费代理池项目:proxy_pool
互动话题:你在爬虫开发中遇到过最棘手的问题是什么?欢迎留言讨论!
本文由「4019研习室」公众号原创,转载请保留出处。👇 关注我们,获取更多技术干货!
 10个月宝宝每天需要喝多少奶粉?