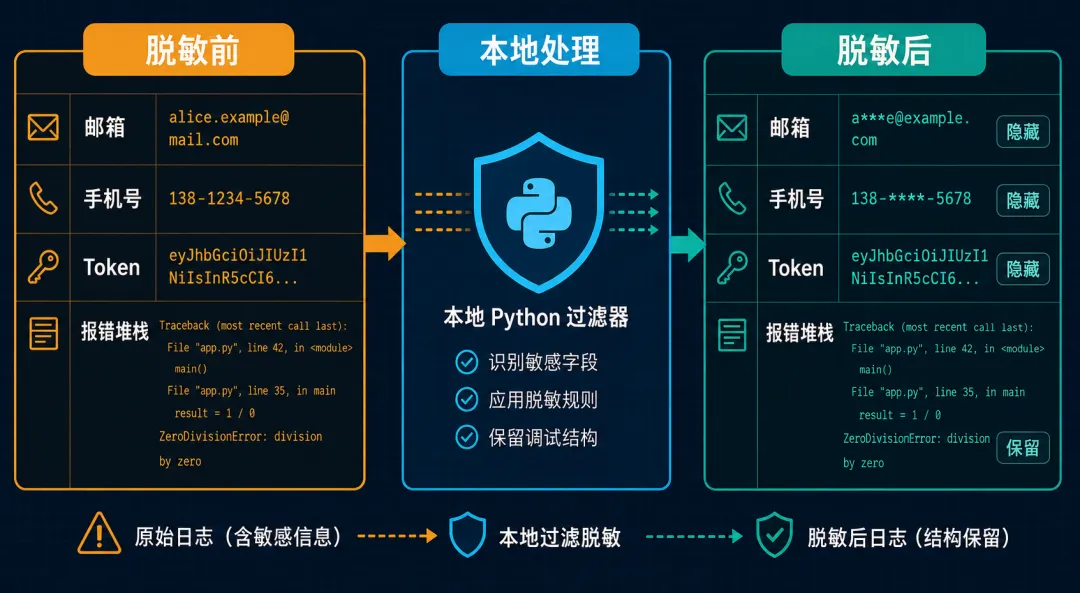
报错日志太长时,我也会想到让 AI 帮忙找问题。
但复制之前最好停一下。日志里除了异常堆栈,还可能混着用户邮箱、手机号、Authorization、API Key 和带 Token 的请求地址。
手动删除并不稳,日志一长就容易漏。更省事的办法,是先在本地跑一次脱敏脚本,只把处理后的副本交给 AI。
这个脚本处理什么
下面的脚本默认识别:
Authorization: Bearer ...api_key、token、password、secret 等字段;
它不会修改原始日志,也不会删除 Traceback、文件名、行号和异常类型。
完整代码
保存为 redact_log.py:
from __future__ import annotationsimport argparseimport refrom collections.abc import Callablefrom pathlib import PathReplacement = str | Callable[[re.Match[str]], str]def mask_email(match: re.Match[str]) -> str: local, domain = match.group(1), match.group(2) visible = local[0] if local else "*" return f"{visible}***@{domain}"RULES: list[tuple[str, re.Pattern[str], Replacement]] = [ ( "authorization", re.compile( r"(?i)(\bAuthorization\s*[:=]\s*Bearer\s+)" r"[A-Za-z0-9._~+/=-]{8,}" ), r"\1***", ), ( "url_secret", re.compile( r"(?i)([?&](?:api[_-]?key|access[_-]?token|" r"token|secret)=)[^&\s]+" ), r"\1***", ), ( "named_secret", re.compile( r'''(?ix) (?<![?&]) (?P<prefix> ["']?(?:api[_-]?key|access[_-]?token| token|password|passwd|secret)["']? \s*[:=]\s* ) (?P<quote>["']?) (?P<value>[^\s,&"'}]+) (?P=quote) ''' ), lambda m: ( f"{m.group('prefix')}" f"{m.group('quote')}***{m.group('quote')}" ), ), ( "email", re.compile( r"(?<![\w.+-])([\w.+-]+)@" r"([A-Za-z0-9-]+(?:\.[A-Za-z0-9-]+)+)" ), mask_email, ), ( "cn_mobile", re.compile( r"(?<!\d)(1[3-9]\d)(\d{4})(\d{4})(?!\d)" ), r"\1****\3", ),]def redact_text(text: str) -> tuple[str, dict[str, int]]: counts: dict[str, int] = {} result = text for name, pattern, replacement in RULES: result, count = pattern.subn(replacement, result) if count: counts[name] = count return result, countsdef parse_args() -> argparse.Namespace: parser = argparse.ArgumentParser( description=( "Redact common secrets and personal data " "from a UTF-8 log file." ) ) parser.add_argument( "input", type=Path, help="Source log file", ) parser.add_argument( "-o", "--output", type=Path, required=True, help="Redacted log file", ) parser.add_argument( "--overwrite", action="store_true", help="Allow replacing an existing output file", ) return parser.parse_args()def main() -> int: args = parse_args() source = args.input.expanduser().resolve() output = args.output.expanduser().resolve() if not source.is_file(): raise SystemExit( f"Input file does not exist: {source}" ) if source == output: raise SystemExit( "Input and output must be different files" ) if output.exists() and not args.overwrite: raise SystemExit( f"Output already exists: {output} " "(use --overwrite to replace it)" ) if not output.parent.is_dir(): raise SystemExit( f"Output directory does not exist: {output.parent}" ) try: original = source.read_text(encoding="utf-8") except UnicodeDecodeError as exc: raise SystemExit( "Input is not valid UTF-8; " "convert its encoding first" ) from exc redacted, counts = redact_text(original) output.write_text(redacted, encoding="utf-8") total = sum(counts.values()) details = ", ".join( f"{name}={count}" for name, count in counts.items() ) or "none" print(f"Redacted {total} item(s): {details}") print(f"Wrote: {output}") return 0if __name__ == "__main__": raise SystemExit(main())
脚本需要 Python 3.10 或更高版本,不依赖第三方包。
运行方法
python redact_log.py app.log -o app.redacted.log
如果目标文件已经存在,需要明确允许覆盖:
python redact_log.py app.log \ -o app.redacted.log \ --overwrite
假设原始日志是:
Authorization: Bearer abc.def-123456789email=alice.dev@example.comphone=13812345678api_key='sk-demo-123456'url=https://example.com/run?token=query-secret&mode=debugValueError: request failed
处理后会变成:
Authorization: Bearer ***email=a***@example.comphone=138****5678api_key='***'url=https://example.com/run?token=***&mode=debugValueError: request failed
可以看到,Token 被隐藏了,但 URL 后面的 mode=debug 仍然保留。异常类型、文件路径和行号也不会受到影响。
使用前还要注意
正则脱敏不是万能的。
项目可能使用自定义字段,例如 private_code、session_id 或业务内部密钥。遇到这种情况,需要继续往 RULES 中增加规则。
另外,脚本生成的是脱敏副本,不代表一定没有遗漏。真正发送给外部 AI 工具前,最好再人工搜索一次:
passwordtokensecretkeyAuthorization
如果日志涉及公司源码、用户数据或其他机密,即使经过正则脱敏,也不应该直接提交到未经确认的外部服务。
Python 官方文档建议复杂场景使用预编译正则对象;subn() 还能同时返回替换后的文本和替换次数,正好适合统计本次处理了多少项。Python re 官方文档
如果想在程序输出日志时直接脱敏,可以继续把相同规则接入 logging.Filter。过滤器可以在 Handler 输出日志前检查或修改记录。Python logging 官方文档
如果平时长期使用 ChatGPT、Claude、Cursor 或 Kiro,也可以了解 gpt68.com。它是第三方 AI 会员充值平台,使用前应看清套餐说明、账号要求和售后规则。工具能不能写代码是一方面,提交给工具的内容是否安全,同样值得注意。