Linux内存管理:内存规整
- 2026-09-07 01:32:39
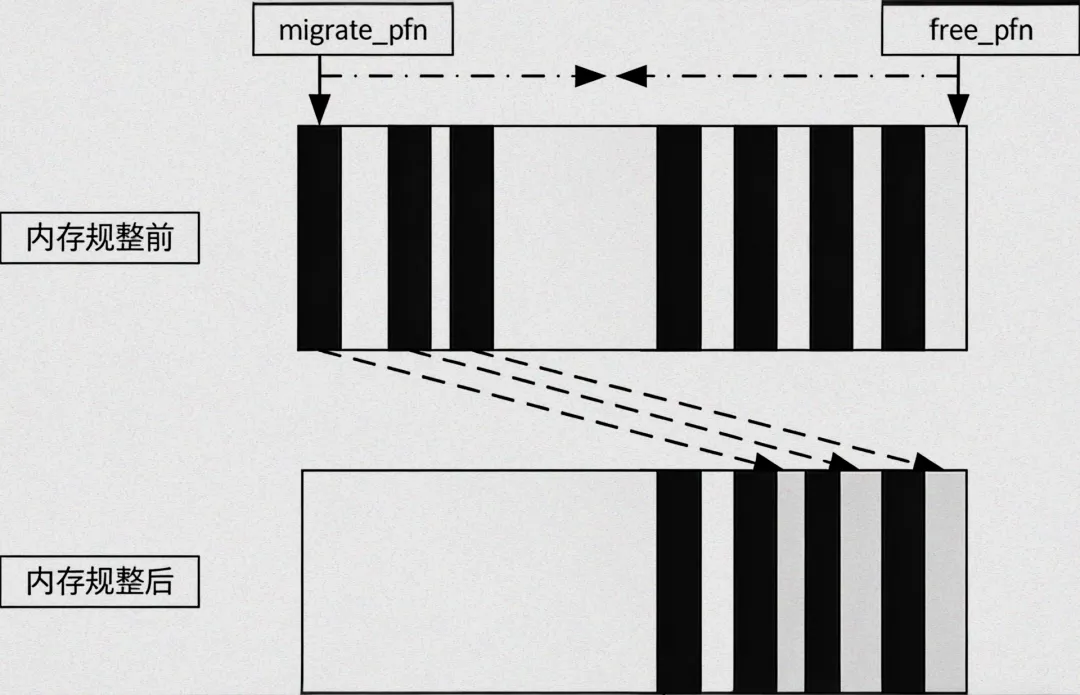
内存规整也即内存碎片整理,内存碎片也是以页面为单位的。实现基础是内存页面按照可移动性进行分组。内存规整的实现基础是页面迁移。
Linux内核以pageblock为单位来管理页的迁移属性。
为什么需要内存规整?
有些情况下,物理设备需要大段连续物理内存。虽然此时空闲内存足够,但是哟与无法找到连续的物理内存,仍然造成内存分配失败。
一、内存规整的触发
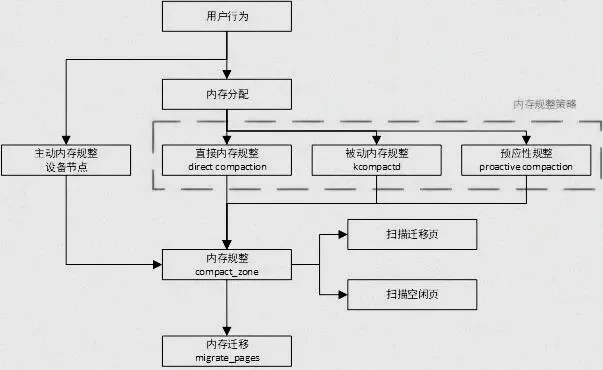
下面是内存页面分配,以及分配失败之后采取的措施,以便促成分配成功。
alloc_pages-------------------------------------页面分配的入口->__alloc_pages_nodemask->get_page_from_freelist--------------------直接从zonelist的空闲列表中分配页面->__alloc_pages_slowpath--------------------在初次尝试分配失败后,进入slowpath路径分配页面->wake_all_kswapds------------------------唤醒kswapd内核线程进行页面回收->get_page_from_freelist------------------kswapd页面回收后再次进行页面分配->__alloc_pages_direct_compact------------进行页面规整,然后进行页面分配->__alloc_pages_direct_reclaim------------直接页面回收,然后进行页面分配->__alloc_pages_may_oom-------------------尝试触发OOM
可以看出采取的措施,越来越重。首先采用kswapd来进行页面回收,然后尝试页面规整、直接页面回收,最后是OOM杀死进程来获取更多内存空间。
另一条路径是在kswapd的balance_pgdat中会判断是否需要进行内存规整。
kswapd->balance_pgdat-------------------------------遍历内存节点的zone,判断是否处于平衡状态即WMARK_HIGH。->compact_pgdat-----------------------------针对整个内存节点进行内存规整
其中compact_pddat->compact_pgdat->compact_zone,最终的实现和alloc_pages_direct_compact调用compact_zone一样。
1.1 内存规整相关节点
内存规整相关有两个节点,compact_memory用于触发内存规整;extfrag_threshold影响内核决策是采用内存规整还是直接回收来满足大内存分配。
节点入口代码:
static struct ctl_table vm_table[] = {...#ifdef CONFIG_COMPACTION{.procname = "compact_memory",.data = &sysctl_compact_memory,.maxlen = sizeof(int),.mode = 0200,.proc_handler = sysctl_compaction_handler,},{.procname = "extfrag_threshold",.data = &sysctl_extfrag_threshold,.maxlen = sizeof(int),.mode = 0644,.proc_handler = sysctl_extfrag_handler,.extra1 = &min_extfrag_threshold,.extra2 = &max_extfrag_threshold,},#endif/* CONFIG_COMPACTION */...{ }}
1.1.1 /proc/sys/vm/compact_memory
打开compaction Tracepoint:echo 1 > /sys/kernel/debug/tracing/events/compaction/enable
触发内存规整:sysctl -w vm.compact_memory=1
查看Tracepoint:cat /sys/kernel/debug/tracing/trace
1.1.2 /proc/sys/vm/extfrag_threshold
在compact_zone中调用函数compaction_suitable->__compaction_suitable进行判断是否进行内存规整。
和extfrag_threshold相关部分如下,如果当前fragindex不超过sysctl_extfrag_threshold,则不会继续进行内存规整。
所以这个参数越小越倾向于进行内存规整,越大越不容易进行内存规整。
static unsigned long __compaction_suitable(struct zone *zone, int order,int alloc_flags, int classzone_idx){...fragindex = fragmentation_index(zone, order);if (fragindex >= 0 && fragindex <= sysctl_extfrag_threshold)return COMPACT_NOT_SUITABLE_ZONE;return COMPACT_CONTINUE;}
设置extfrag_threshold:sysctl -w vm.extfrag_threshold=500
1.1.3 其它Debug信息
/sys/kernel/debug/extfrag/extfrag_index
/sys/kernel/debug/extfrag/unusable_index
二、内存规整实现
在进入细节前,先看看内存规整函数框架。
__alloc_pages_direct_compact->try_to_compact_pages-----------------直接内存规整来满足高阶分配需求->compact_zone_order-----------------遍历zonelist对每个zone进行规整->compact_zone---------------------对zone进行规整 ->compaction_suitable------------检查是否继续规整,COMPACT_PARTIAL/COMPACT_SKIPPED都跳过。->compact_finished---------------在while中判断是否可以停止内存规整->isolate_migratepages-----------查找可以迁移页面 ->migrate_pages------------------进行页面迁移操作->get_free_page_from_freelist------在规整完成后进行页面分配操作
__alloc_pages_direct_compact首先执行规整操作,然后进行页面分配。
static struct page *__alloc_pages_direct_compact(gfp_t gfp_mask, unsigned int order,int alloc_flags, const struct alloc_context *ac,enum migrate_mode mode, int *contended_compaction,bool *deferred_compaction){unsigned long compact_result;struct page *page;if (!order)-----------------------------------------------------------------order为0情况,不用进行内存规整。return NULL;current->flags |= PF_MEMALLOC;compact_result = try_to_compact_pages(gfp_mask, order, alloc_flags, ac,-----进行内存规整,当前进程会置PF_MEMALLOC,避免进程迁移时发生死锁。mode, contended_compaction);current->flags &= ~PF_MEMALLOC;switch (compact_result) {case COMPACT_DEFERRED:*deferred_compaction = true;/* fall-through */case COMPACT_SKIPPED:return NULL;default:break;}...page = get_page_from_freelist(gfp_mask, order,-----------------------------进行内存分配alloc_flags & ~ALLOC_NO_WATERMARKS, ac);...count_vm_event(COMPACTFAIL);cond_resched();return NULL;}
try_to_compact_pages执行内存规整,以pageblock为单位,选择pageblock中可迁移页面。
unsignedlongtry_to_compact_pages(gfp_t gfp_mask, unsignedint order,int alloc_flags, const struct alloc_context *ac,enum migrate_mode mode, int *contended){int may_enter_fs = gfp_mask & __GFP_FS;int may_perform_io = gfp_mask & __GFP_IO;struct zoneref *z;struct zone *zone;int rc = COMPACT_DEFERRED;int all_zones_contended = COMPACT_CONTENDED_LOCK; /* init for &= op */*contended = COMPACT_CONTENDED_NONE;/* Check if the GFP flags allow compaction */if (!order || !may_enter_fs || !may_perform_io)return COMPACT_SKIPPED;trace_mm_compaction_try_to_compact_pages(order, gfp_mask, mode);/* Compact each zone in the list */for_each_zone_zonelist_nodemask(zone, z, ac->zonelist, ac->high_zoneidx,-----------根据掩码遍历特定zoneac->nodemask) {int status;int zone_contended;if (compaction_deferred(zone, order))continue;status = compact_zone_order(zone, order, gfp_mask, mode,-----------------------针对特定zone进行规整&zone_contended, alloc_flags,ac->classzone_idx);rc = max(status, rc);/** It takes at least one zone that wasn't lock contended* to clear all_zones_contended.*/all_zones_contended &= zone_contended;/* If a normal allocation would succeed, stop compacting */if (zone_watermark_ok(zone, order, low_wmark_pages(zone),ac->classzone_idx, alloc_flags)) {--------------------------------当前zoen水位是否高于WMARK_LOW,如果是则退出当前循环。/** We think the allocation will succeed in this zone,* but it is not certain, hence the false. The caller* will repeat this with true if allocation indeed* succeeds in this zone.*/compaction_defer_reset(zone, order, false);/** It is possible that async compaction aborted due to* need_resched() and the watermarks were ok thanks to* somebody else freeing memory. The allocation can* however still fail so we better signal the* need_resched() contention anyway (this will not* prevent the allocation attempt).*/if (zone_contended == COMPACT_CONTENDED_SCHED)*contended = COMPACT_CONTENDED_SCHED;goto break_loop;}...continue;break_loop:/** We might not have tried all the zones, so be conservative* and assume they are not all lock contended.*/all_zones_contended = 0;break;}/** If at least one zone wasn't deferred or skipped, we report if all* zones that were tried were lock contended.*/if (rc > COMPACT_SKIPPED && all_zones_contended)*contended = COMPACT_CONTENDED_LOCK;return rc;}
compact_zone_order调用compact_zone,最主要的就是将参数填入struct compact_control结构体,然后和zone一起作为参数传递给compact_zone。
struct compact_control数据结构记录了被迁移的页面,以及规整过程中迁移到的页面列表。
staticunsignedlongcompact_zone_order(struct zone *zone, int order,gfp_t gfp_mask, enum migrate_mode mode, int *contended,int alloc_flags, int classzone_idx){unsigned long ret;struct compact_control cc = {.nr_freepages = 0,.nr_migratepages = 0,.order = order,------------------------------------------需要规整的页面阶数.gfp_mask = gfp_mask,------------------------------------页面规整的页面掩码.zone = zone,.mode = mode,--------------------------------------------页面规整模式-同步、异步.alloc_flags = alloc_flags,.classzone_idx = classzone_idx,};INIT_LIST_HEAD(&cc.freepages);-------------------------------初始化迁移目的地的链表INIT_LIST_HEAD(&cc.migratepages);----------------------------初始化将要迁移页面链表ret = compact_zone(zone, &cc);VM_BUG_ON(!list_empty(&cc.freepages));VM_BUG_ON(!list_empty(&cc.migratepages));*contended = cc.contended;return ret;}staticintcompact_zone(struct zone *zone, struct compact_control *cc){int ret;unsigned long start_pfn = zone->zone_start_pfn;unsigned long end_pfn = zone_end_pfn(zone);const int migratetype = gfpflags_to_migratetype(cc->gfp_mask);const bool sync = cc->mode != MIGRATE_ASYNC;unsigned long last_migrated_pfn = 0;ret = compaction_suitable(zone, cc->order, cc->alloc_flags,cc->classzone_idx);-------------------------------根据当前zone水位来判断是否需要进行内存规整,COMPACT_CONTINUE表示可以做内存规整。switch (ret) {case COMPACT_PARTIAL:case COMPACT_SKIPPED:/* Compaction is likely to fail */return ret;case COMPACT_CONTINUE:/* Fall through to compaction */;}/** Clear pageblock skip if there were failures recently and compaction* is about to be retried after being deferred. kswapd does not do* this reset as it'll reset the cached information when going to sleep.*/if (compaction_restarting(zone, cc->order) && !current_is_kswapd())__reset_isolation_suitable(zone);/** Setup to move all movable pages to the end of the zone. Used cached* information on where the scanners should start but check that it* is initialised by ensuring the values are within zone boundaries.*/cc->migrate_pfn = zone->compact_cached_migrate_pfn[sync];-----------------表示从zone的开始页面开始扫描和查找哪些页面可以被迁移。cc->free_pfn = zone->compact_cached_free_pfn;-----------------------------从zone末端开始扫描和查找哪些空闲的页面可以用作迁移页面的目的地。if (cc->free_pfn < start_pfn || cc->free_pfn > end_pfn) {-----------------下面对free_pfn和migrate_pfn进行范围限制。cc->free_pfn = end_pfn & ~(pageblock_nr_pages-1);zone->compact_cached_free_pfn = cc->free_pfn;}if (cc->migrate_pfn < start_pfn || cc->migrate_pfn > end_pfn) {cc->migrate_pfn = start_pfn;zone->compact_cached_migrate_pfn[0] = cc->migrate_pfn;zone->compact_cached_migrate_pfn[1] = cc->migrate_pfn;}trace_mm_compaction_begin(start_pfn, cc->migrate_pfn,cc->free_pfn, end_pfn, sync);migrate_prep_local();while ((ret = compact_finished(zone, cc, migratetype)) ==COMPACT_CONTINUE) {-----------------------------------while中从zone开头扫描查找合适的迁移页面,然后尝试迁移到zone末端空闲页面中,直到zone处于低水位WMARK_LOW之上。int err;unsigned long isolate_start_pfn = cc->migrate_pfn;switch (isolate_migratepages(zone, cc)) {-----------------------------用于扫描和查找合适迁移的页,从zone头部开始找起,查找步长以pageblock_nr_pages为单位。case ISOLATE_ABORT:ret = COMPACT_PARTIAL;putback_movable_pages(&cc->migratepages);cc->nr_migratepages = 0;goto out;case ISOLATE_NONE:/** We haven't isolated and migrated anything, but* there might still be unflushed migrations from* previous cc->order aligned block.*/goto check_drain;case ISOLATE_SUCCESS:;}err = migrate_pages(&cc->migratepages, compaction_alloc,--------------migrate_pages是页面迁移核心函数,从cc->migratepages中摘取页,然后尝试去迁移。compaction_free, (unsigned long)cc, cc->mode,MR_COMPACTION);trace_mm_compaction_migratepages(cc->nr_migratepages, err,&cc->migratepages);/* All pages were either migrated or will be released */cc->nr_migratepages = 0;if (err) {------------------------------------------------------------没处理成功的页面会放回到合适的LRU链表中。putback_movable_pages(&cc->migratepages);/** migrate_pages() may return -ENOMEM when scanners meet* and we want compact_finished() to detect it*/if (err == -ENOMEM && cc->free_pfn > cc->migrate_pfn) {ret = COMPACT_PARTIAL;goto out;}}...}out:...trace_mm_compaction_end(start_pfn, cc->migrate_pfn,cc->free_pfn, end_pfn, sync, ret);return ret;}
compaction_suitable根据当前zone水位决定是否需要继续内存规整,主要工作由__compaction_suitable进行处理。
主要依据zone低水位和extfrag_threshold两个参数进行判断。
unsignedlongcompaction_suitable(struct zone *zone, int order,int alloc_flags, int classzone_idx){unsigned long ret;ret = __compaction_suitable(zone, order, alloc_flags, classzone_idx);trace_mm_compaction_suitable(zone, order, ret);if (ret == COMPACT_NOT_SUITABLE_ZONE)ret = COMPACT_SKIPPED;return ret;}static unsigned long __compaction_suitable(struct zone *zone, int order,int alloc_flags, int classzone_idx){int fragindex;unsigned long watermark;/** order == -1 is expected when compacting via* /proc/sys/vm/compact_memory*/if (order == -1)return COMPACT_CONTINUE;watermark = low_wmark_pages(zone);/** If watermarks for high-order allocation are already met, there* should be no need for compaction at all.*/if (zone_watermark_ok(zone, order, watermark, classzone_idx,alloc_flags))--------------------------------------COMPACT_PARTIAL:如果满足低水位,则不需要进行内存规整。return COMPACT_PARTIAL;/** Watermarks for order-0 must be met for compaction. Note the 2UL.* This is because during migration, copies of pages need to be* allocated and for a short time, the footprint is higher*/watermark += (2UL << order);---------------------------------------------------增加水位高度为watermark+2<<order。if (!zone_watermark_ok(zone, 0, watermark, classzone_idx, alloc_flags))--------COMPACT_SKIPPED:如果达不到新水位,说明当前zone中空闲页面很少,不适合作内存规整,跳过此zone。return COMPACT_SKIPPED;/** fragmentation index determines if allocation failures are due to* low memory or external fragmentation** index of -1000 would imply allocations might succeed depending on* watermarks, but we already failed the high-order watermark check* index towards 0 implies failure is due to lack of memory* index towards 1000 implies failure is due to fragmentation** Only compact if a failure would be due to fragmentation.*/fragindex = fragmentation_index(zone, order);if (fragindex >= 0 && fragindex <= sysctl_extfrag_threshold)-----------------由extfrag_threshold控制的内存规整流程return COMPACT_NOT_SUITABLE_ZONE;return COMPACT_CONTINUE;}
compact_finished判断内存规整流程是否可以结束,结束的条件有两个:
一是cc->migrate_pfn和cc->free_pfn两个指针相遇;二是以order为条件判断当前zone的水位在低水位之上。
staticintcompact_finished(struct zone *zone, struct compact_control *cc,const int migratetype){int ret;ret = __compact_finished(zone, cc, migratetype);trace_mm_compaction_finished(zone, cc->order, ret);if (ret == COMPACT_NO_SUITABLE_PAGE)ret = COMPACT_CONTINUE;return ret;}static int __compact_finished(struct zone *zone, struct compact_control *cc,const int migratetype){unsigned int order;unsigned long watermark;if (cc->contended || fatal_signal_pending(current))return COMPACT_PARTIAL;/* Compaction run completes if the migrate and free scanner meet */if (cc->free_pfn <= cc->migrate_pfn) {-----------------------------------------扫描可迁移页面和空闲页面,从zone的头尾向中间运行。当两者相遇,可以停止规整。/* Let the next compaction start anew. */zone->compact_cached_migrate_pfn[0] = zone->zone_start_pfn;zone->compact_cached_migrate_pfn[1] = zone->zone_start_pfn;zone->compact_cached_free_pfn = zone_end_pfn(zone);/** Mark that the PG_migrate_skip information should be cleared* by kswapd when it goes to sleep. kswapd does not set the* flag itself as the decision to be clear should be directly* based on an allocation request.*/if (!current_is_kswapd())zone->compact_blockskip_flush = true;return COMPACT_COMPLETE;--------------------------------------------------停止内存规整}/** order == -1 is expected when compacting via* /proc/sys/vm/compact_memory*/if (cc->order == -1)----------------------------------------------------------order为-1表示强制执行内存规整,继续内存规整return COMPACT_CONTINUE;/* Compaction run is not finished if the watermark is not met */watermark = low_wmark_pages(zone);if (!zone_watermark_ok(zone, cc->order, watermark, cc->classzone_idx,cc->alloc_flags))--------------------------------------不满足低水位条件,继续内存规整。return COMPACT_CONTINUE;/* Direct compactor: Is a suitable page free? */for (order = cc->order; order < MAX_ORDER; order++) {struct free_area *area = &zone->free_area[order];/* Job done if page is free of the right migratetype */if (!list_empty(&area->free_list[migratetype]))----------------------------空闲页面为空,无法进行迁移,停止内存规整。return COMPACT_PARTIAL;/* Job done if allocation would set block type */if (order >= pageblock_order && area->nr_free)return COMPACT_PARTIAL;}return COMPACT_NO_SUITABLE_PAGE;}
isolate_migratepages扫描并寻找zone中可迁移页面,结果会添加到cc->migratepages链表中。
扫描的一个重要参数是页的迁移属性参考MIGRATE_TYPES。
Linux内核以pageblock为单位来管理页的迁移属性,一个pageblock大小为4MB大小,即2^10个页面。
pageblock_nr_pages即为1024个页面。
staticisolate_migrate_tisolate_migratepages(struct zone *zone,struct compact_control *cc){unsigned long low_pfn, end_pfn;struct page *page;const isolate_mode_t isolate_mode =(cc->mode == MIGRATE_ASYNC ? ISOLATE_ASYNC_MIGRATE : 0);/** Start at where we last stopped, or beginning of the zone as* initialized by compact_zone()*/low_pfn = cc->migrate_pfn;/* Only scan within a pageblock boundary */end_pfn = ALIGN(low_pfn + 1, pageblock_nr_pages);/** Iterate over whole pageblocks until we find the first suitable.* Do not cross the free scanner.*/for (; end_pfn <= cc->free_pfn;---------------------------------------从cc->migrate_pfn开始以pageblock_nr_pages为步长向zone尾部进行扫描。low_pfn = end_pfn, end_pfn += pageblock_nr_pages) {/** This can potentially iterate a massively long zone with* many pageblocks unsuitable, so periodically check if we* need to schedule, or even abort async compaction.*/if (!(low_pfn % (SWAP_CLUSTER_MAX * pageblock_nr_pages))&& compact_should_abort(cc))break;page = pageblock_pfn_to_page(low_pfn, end_pfn, zone);if (!page)continue;/* If isolation recently failed, do not retry */if (!isolation_suitable(cc, page))continue;/** For async compaction, also only scan in MOVABLE blocks.* Async compaction is optimistic to see if the minimum amount* of work satisfies the allocation.*/if (cc->mode == MIGRATE_ASYNC &&!migrate_async_suitable(get_pageblock_migratetype(page)))----migrate_async_suitable判断pageblock是否是MIGRATE_MOVABLE和MIGRATE_CMA两种类型,这两种类型可以迁移。continue;/* Perform the isolation */low_pfn = isolate_migratepages_block(cc, low_pfn, end_pfn,isolate_mode);---------------------------扫描和分离pageblock中的页面是否是和迁移。if (!low_pfn || cc->contended) {acct_isolated(zone, cc);return ISOLATE_ABORT;}/** Either we isolated something and proceed with migration. Or* we failed and compact_zone should decide if we should* continue or not.*/break;}acct_isolated(zone, cc);/** Record where migration scanner will be restarted. If we end up in* the same pageblock as the free scanner, make the scanners fully* meet so that compact_finished() terminates compaction.*/cc->migrate_pfn = (end_pfn <= cc->free_pfn) ? low_pfn : cc->free_pfn;return cc->nr_migratepages ? ISOLATE_SUCCESS : ISOLATE_NONE;}
compaction_alloc()从zone的末尾开始查找空闲页面,并把空闲页面添加到cc->freepages链表中。然后从cc->freepages中摘除页面,返回给migrate_pages作为迁移使用。
compaction_free是规整失败的处理函数,将空闲页面返回给cc->freepages。
static struct page *compaction_alloc(struct page *migratepage,unsigned long data,int **result){struct compact_control *cc = (struct compact_control *)data;struct page *freepage;/** Isolate free pages if necessary, and if we are not aborting due to* contention.*/if (list_empty(&cc->freepages)) {if (!cc->contended)isolate_freepages(cc);--------------------------------------查找可以用来作为迁移目的页面if (list_empty(&cc->freepages))---------------------------------如果没有页面可被用来作为迁移目的页面,返回NULL。return NULL;}freepage = list_entry(cc->freepages.next, struct page, lru);list_del(&freepage->lru);-------------------------------------------将空闲页面从cc->freepages中摘除。cc->nr_freepages--;return freepage;----------------------------------------------------找到可以被用作迁移目的的页面}staticvoidcompaction_free(struct page *page, unsignedlong data){struct compact_control *cc = (struct compact_control *)data;list_add(&page->lru, &cc->freepages);-------------------------------失败情况下,将页面放回cc->freepages。cc->nr_freepages++;}
Linux内存管理系列文章:
原作者:ArnoldLu
原文地址:
https://www.cnblogs.com/arnoldlu/p/8335532.html
